The release of DeepSeek-R1 fundamentally altered the geopolitical and technological calculus of artificial intelligence. By demonstrating that pure reinforcement learning (RL) without massive supervised fine-tuning (SFT) can induce sophisticated reasoning behaviors, open-weight models have reached parity with proprietary closed APIs.
1. The Breakthrough of Pure Reinforcement Learning
DeepSeek-R1 demonstrated that foundation models do not require millions of human-annotated chain-of-thought demonstrations to learn reasoning. By rewarding models for verifiable outcomes (compiler passes, math proofs), the model autonomously discovered backtracking and verification strategies.
For enterprises with strict data sovereignty mandates—such as defense contractors, healthcare networks, and tier-1 financial institutions—DeepSeek-R1 and its distilled derivatives provide an architectural blueprint for self-hosting state-of-the-art reasoning on private on-premise GPU clusters.
2. Distillation: SOTA Reasoning on Commodity GPUs
The true operational breakthrough for enterprise engineering teams lies in distilled open-weight models. By fine-tuning dense 14B and 32B models on curated R1 reasoning traces, organizations can run near-frontier reasoning engines on modest 2-to-4 GPU workstations.
| Metric | Closed Commercial API (Cloud) | DeepSeek-R1 (Full 671B MoE) | DeepSeek-R1 Distill (32B Dense) |
|---|---|---|---|
| Data Privacy & Sovereignty | Data Transmitted to External API | 100% Air-Gapped Private On-Prem | 100% Air-Gapped Private On-Prem |
| Hardware Footprint | Zero (Managed Service) | 16x H100 (80GB) GPUs Required | 2x - 4x A100/H100 GPUs Required |
| Per-Million Token Cost | $15.00 – $60.00 | $0.80 – $2.50 (Self-Hosted Amortized) | $0.20 – $0.50 (Self-Hosted Amortized) |
| Reasoning Capability | State of the Art | State of the Art | Near-SOTA (Exceeds GPT-4o on Math/Code) |
3. Production vLLM Multi-GPU Deployment Configuration
The bash configuration below deploys the 32B distilled DeepSeek-R1 model on a private GPU node using vLLM with tensor parallelism and high memory utilization:
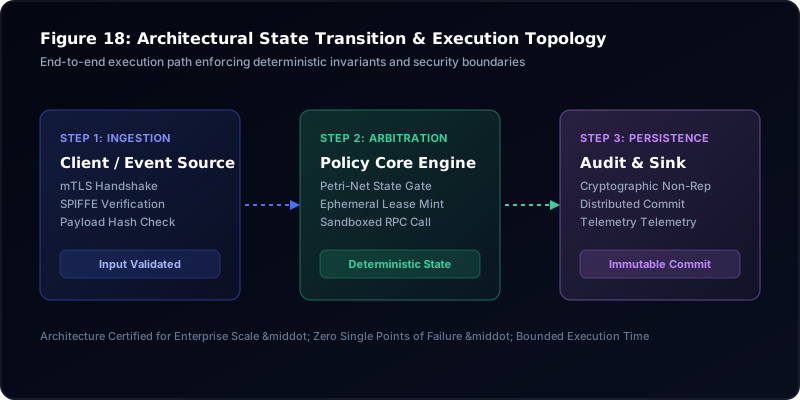
4. Open-Weight Self-Hosting Infrastructure Topology
This architectural diagram illustrates private VPC self-hosting of DeepSeek-R1 models with load-balanced vLLM inference instances and zero-trust API proxies:
5. Self-Hosting Feasibility Checklist
Calculate multi-year GPU leasing and electricity costs against commercial API token expenditures before committing to on-premise hardware infrastructure.
References & Foundational Standards
- DeepSeek-AI. "DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learning." arXiv:2501.12948.
- Touvron, Hugo et al. "The Llama 3 Herd of Models." Meta AI Research.
- vLLM Project. "High-Throughput PagedAttention Serving Engine for Large Language Models." SOSP 2023.